 Latency, or the voice-to-voice delay between the moment a caller has finished speaking and the moment the bot starts talking, determines in many cases whether a conversation with a voicebot feels natural or not. In this knowledge article, we compare two architectures: the direct speech-to-speech (S2S) approach and the classic cascade of speech-to-text, language model, and text-to-speech.
Latency in a conversation between a customer and a voicebot is not always problematic. In a typical face-to-face conversation, the turn-taking between two speakers involves an average transition time of 200 milliseconds. For Dutch, that average is often even slightly shorter. If one of the speakers receives feedback during a face-to-face conversation, or can deduce from the context that a response will take a little longer, this is generally not perceived as problematic. The average duration of a turn-taking varies by country. 200 milliseconds is often cited as the standard for turn-taking time in an acceptably functioning conversation, but in practice, the perception of latency depends on many factors. Even within a single conversation, different forms of delay may or may not be acceptable.
Situation-dependent
For example, slightly longer latency is not a problem if a voicebot needs to look something up in a system (and potentially notify the user). This is something customer service representatives regularly do in practice. In other words, the impact of latency is situation-dependent. However, you can only assess this once you know exactly what was measured, across how many concurrent calls, and regarding which part of the processing chain.
This situational dependency also applies to the advantages and disadvantages of the two common architectures: the cascade model and the speech-to-speech model. Neither is 'the best solution,' and you can even choose to use both approaches side by side.
The cascade or pipeline model
The classic approach is also referred to as the cascade or cascaded pipeline. In this architecture, various intermediate steps are taken repeatedly.
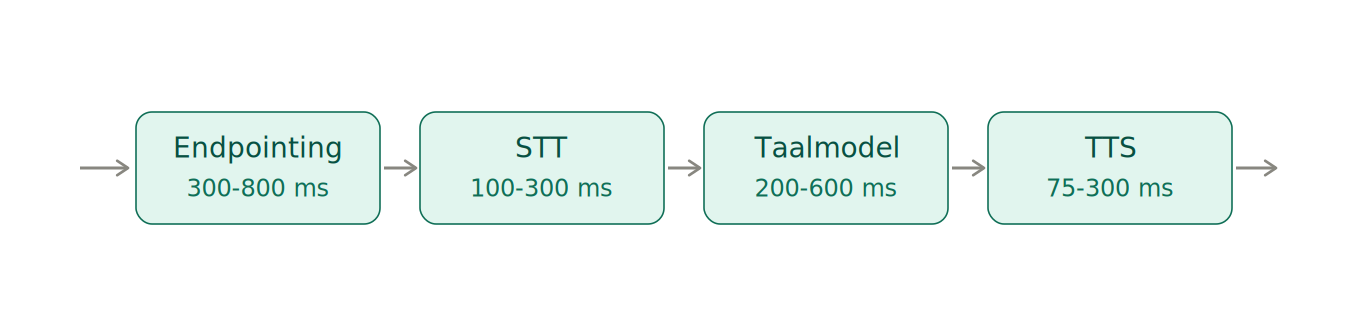
First, the bot must determine whether the speaker has finished speaking. With a green light, speech-to-text (STT) converts the caller's speech into text. That text goes to a language model (LLM) which subsequently determines what the bot should provide as an answer. When necessary, the bot retrieves information from a knowledge base, a CRM application, or a RAG coupling or a combination thereof. If the answer is formulated in text, text-to-speech (TTS) converts that answer back into speech. Each step in these models can make use of streaming, where processing takes place while the caller is still speaking.
Take turns
Endpointing is the moment the bot designates as the point at which the caller has finished speaking. To achieve this, in addition to a fixed waiting time, an acoustic measurement by a voice activity detector (VAD)Fine-tuning this turn-taking process as tightly as possible can save a lot of time in a dialogue with a voicebot. However, settings that are too tight can cause turn-taking to go wrong because the bot starts responding before the caller is finished. There are solutions that also base turn-taking on semantic analysis—that is, on word choice, sentence structure, and intonation—to increase effectiveness.
Each step can be executed using various solutions, each with its own processing time. Benchmarks for these processing times are available for each technology; however, what applies today may be outdated tomorrow because the underlying technology has improved. Additionally, virtually every processing step requires time for data exchange from one technology to another, which depends on the quality of the network and the connections.
Due to streaming, the steps overlap, causing the sum to be higher than reality, while the endpointing latency and network processing time are added on top of it.
The influence of network connections on latency – Contact centers using a WebRTC connection have a voice and data channel at their disposal, with that connection remaining permanently open. Customer information (for example, a number or text) can be transmitted along with the data channel. WebRTC Furthermore, the quality of the customer's Wi-Fi, browser, microphone, and network plays a role.
With a so-called PSTN call (the public telephone network), those disadvantages also exist, and in addition to audio, only information about the number (CLI) are passed on and nothing further. In the transport of information about such PSTNMoreover, delay factors such as jitter and conversion speed (from analog to digital) play a role in the line.
The advantage of the various conversion steps in the cascade model is that a transcript of the dialogue is available by default. This can be used for analysis purposes and for compliance applications. The LLM is also the place where other text-based elements such as business rules, guardrails, and a RAG can be configured.
The speech-to-speech model (S2S)
The second architecture model is speech-to-speech. In this case, there is a single solution that processes speech and simultaneously provides a response, without the need for conversion to text. Fewer conversions mean less processing time, and that difference is noticeable in practice. The most well-known is the OpenAI Realtime API with its model generations. gpt-realtime-2 and gpt-realtime-2.1. The OpenAI solution also supports SIPAccording to the developers, Moshi's model comes in at approximately 200 milliseconds, measured on a single GPU in a test setup. That is a model value, not a contact center value. Because Moshi operates in full duplex, there is no endpointing latency, which explains part of the difference compared to the cascade.
Furthermore, the following have not been included: the search time in CRM systems or RAG solutions via API calls required for more complex issues, and the delay originating from the network and the telephony chain. In practice, S2S models yield various values of up to approximately 800 milliseconds (reference date 2026); these values may vary due to various factors. Moreover, values may decrease across the board due to technology improving over time.
Speech-to-speech models are full-duplex, which means that the caller can interrupt the voicebot (barge-in) and that the bot – because it listens during processing – can effectively respond to this. Speech-to-speech works primarily based on audio tokens. S2S solutions are trained on millions of hours of audio material – think of meetings, movies, and news broadcasts. A limitation is that these collections contain little to no customer service conversations; in some sets, telephone calls, regular calls, and synthetic calls have been added to the training material. An example of such a training set can be found at HuggingFace.
Using audio as training material also means that S2S models have an 'understanding' of the verbal properties of speech: intonation, pitch, volume, and speed. This allows speech models to utilize information about emotions and respond effectively to prosody (stress, pitch, rhythm, and tempo). However, this information is not separately labeled or logged in speech models—so you won't find 'customer is angry' anywhere.
Another shortcoming of S2S models is that they can adopt the customer's prosody. This does not contribute to an effective conversation; if a customer starts speaking faster and louder due to increasing anger, it is precisely not the intention for the voicebot to adopt that communication style.
Furthermore, the qualities in this area are limited to the most spoken languages. As languages become smaller, the quality of the technology decreases. This is a point of attention for those working with clients from different countries or language regions.
Transcript
With S2S, a transcript is not necessary for the voicebot to function. However, for many contact centers, such a transcript is essential for compliance and analysis purposes. In some solutions, the transcript comes from a second model that listens in parallel. This is useful for searching, dashboards, and sampling, but not as evidence of what the bot heard or said. Because the second model processes the audio separately, independent of the speech model, the output may deviate from what the voicebot actually heard, containing incorrect words, sometimes even the wrong language, and a delay of several seconds.
The model of Moshi It works differently and generates a transcription where the text originates from the same model as the audio. Those who start working with S2S have a wide range of choices but must also consider the costs for tokens and storage.
You can also choose to use a cascade model or a separate one after all. ASR-run the solution; the voicebot constellation then runs on two architectures simultaneously.
As long as transcription only runs for logging, it costs no time, but as soon as it forms the basis for guardrails that must be able to stop the call, there is a chance that you will sacrifice the latency gain of S2S.
Conversely, the same applies: anyone wishing to monitor sentiment during a conversation using the cascade model must allow other technology to 'listen in' in real time. In this context, the GDPR and the AI Act relevant. Emotion derived from speech is personal data as soon as you record it, and then the retention period and legal basis apply.
Mask latency
There are various techniques to bridge latency. Common solutions include playing the 'employee's' breathing, playing keyboard sounds, explicitly stating that something is being looked up and that it will take a moment, using filler sentences and interjections, or starting with the first sentence of the answer. Incidentally, adding human sounds is debatable, as it creates the impression that a human employee is involved, which is at odds with the transparency obligation under the AI Act.
Costs
Both models utilize rapidly evolving technology. The same applies to the costs: in both cases, they are unpredictable over the longer term. Indications are $0,25 to $0,35 per call minute for S2S solutions; $0,10 per minute or less for cascade solutions (reference date 2026). Furthermore, what is and is not included may vary depending on the tariff model.
What should you pay attention to in latency problems?
Anyone who wants to know the latency of a solution should not look at demos. There are three things to take into account.
1. First of all, ask for the voice-to-voice value, not partial values of latency. It concerns the time between the moment the caller stops talking and the moment the first substantive response from the voicebot is heard. That is the value that contains all sources of delay. In practice, vendors often cite the processing time of the model itself or the time until the first token, and those times quickly turn out to be a factor of two to three more favorable than the actual silence the caller experiences.
2. When doing so, do not ask for the average, but for the p50 and p95 values. The P stands for percentile, also known from, for example, service level reports. The p50 value is the median where one half of the turn changes are faster and the other half slower. The p50 value determines how natural a conversation feels. The p95 value is the value below which 95 percent of the turns remain.
ExampleSuppose your voicebot handles a thousand calls in a day, with about twelve turn-takings in each call. With a p50 of 0,6 seconds and a p95 of 2,4 seconds, the average over those twelve thousand turns is approximately 0,85 seconds. On paper, therefore, you remain well under a second, but on that day, there are six hundred instances of silence lasting more than two seconds. Those six hundred slow turn-takings are spread across all calls, so with twelve turn-takings per call, about half of a thousand customers experience such a delay at least once. With such delays, a caller might think the connection has been broken. Also determining factors are the type of call, the moment in the conversation, and the means by which that delay is potentially filled (the aforementioned 'masking').
3. Request figures based on existing production environments with a reference customer. A demo involves a single session, with optimal infrastructure and an endpoint nearby. In production, all variables play a realistic role: queues, concurrent calls, endpointing delayed by accents, background noise, or a mobile connection, or API calls taking longer than expected.
Ultimately, the choice is not about the architecture, but about which type of conversation tolerates which delay and what your customers are willing to accept.
(Ziptone/editors)


Also interesting
-

According to OpenAI, GPT‑Realtime was developed for use in customer service, among other areas. There is no information yet about the…
-
Speech-to-speech works faster than the 'traditional' voicebot model. Robin van Leyden from Steam-connect provides an explanation.
-

OpenAI's GPT-Realtime-Translate can translate conversations live while someone is speaking, without noticeable delay, according to the company.